AI visibility platform comparison for B2B SaaS: where SEO tools stop and dedicated AI visibility starts
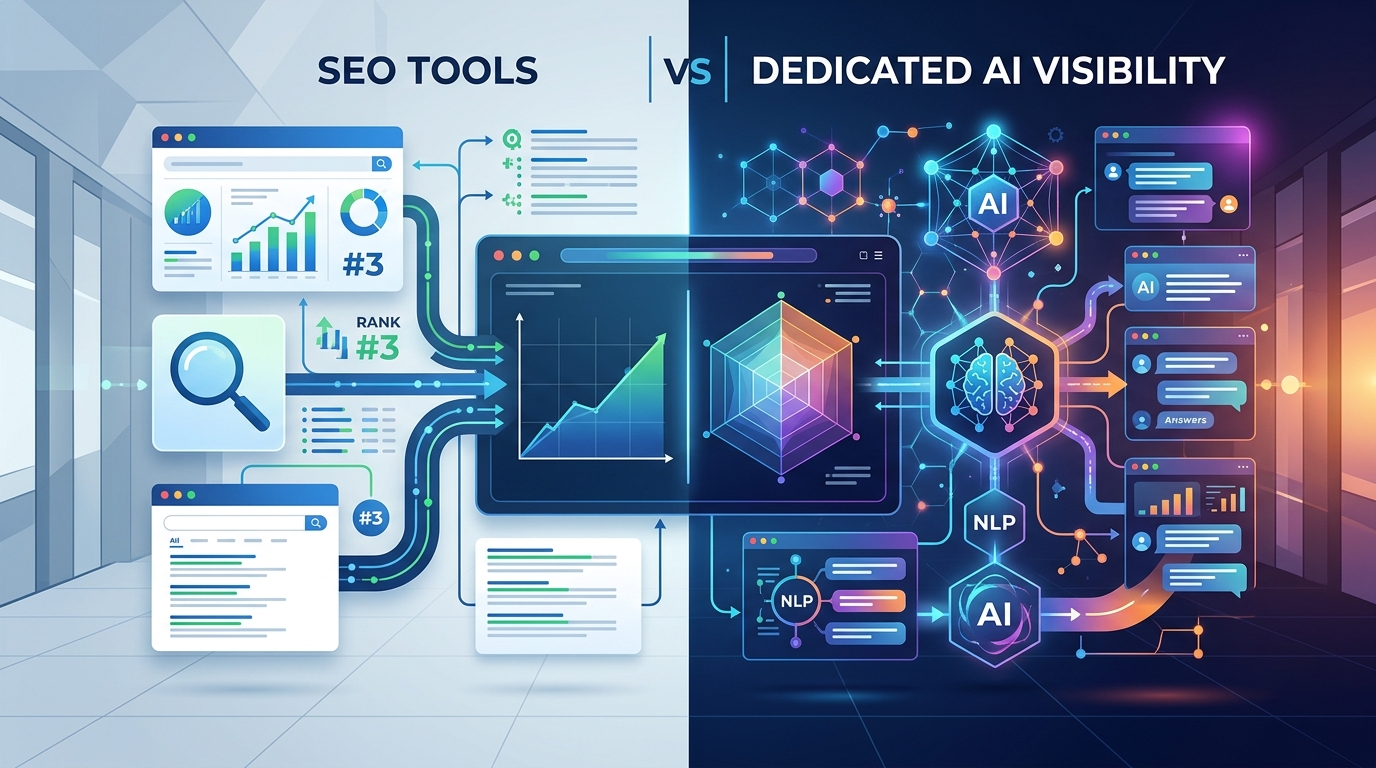
B2B SaaS teams do not need to replace SEO platforms, analytics, or Search Console. They need a missing layer: an AI visibility platform comparison for B2B SaaS starts with one simple fact that traditional stacks cannot answer—how often ChatGPT, Perplexity, Claude, Gemini, and other answer engines mention your brand, cite your pages, or recommend a competitor instead. That is exactly the gap Targetlytics is built to cover.
- Search Console shows search performance, not model recommendations
- Semrush and Ahrefs show keyword and link data, not answer-engine citation paths
- GA4 shows site behavior after a visit, not brand presence inside AI answers
- A dedicated AI visibility platform tracks mentions, citations, recommendation share, and model-by-model variance
That gap matters because buying journeys now start inside answer engines. A prospect asks for “best CRM for healthcare startups” or “top SOC 2 compliance tools for SaaS,” gets a short list, and may never click the ten blue links your SEO program worked to win. If your team cannot track AI mention share across models, compare brand presence in ChatGPT and Perplexity, or explain why competitors are cited in AI answers, you are managing a channel you cannot see.
The real comparison is not platform vs platform. It is stack vs blind spot
An AI visibility platform comparison for B2B SaaS starts with a simple test: can your current stack show where AI systems mention your brand, cite your sources, recommend a competitor, and connect that exposure to pipeline? Search Console, Semrush, Ahrefs, and GA4 still answer ranking and traffic questions, but they do not show what happens inside ChatGPT, Claude, Gemini, or Perplexity answers.
QuestionSearch Console / Semrush / Ahrefs / GA4Dedicated AI visibility platformAre we ranking for target queries?YesSometimes, indirectlyAre AI models mentioning our brand?NoYesWhich competitors are recommended instead?NoYesWhich sources are AI systems citing?NoYesHow does visibility differ across ChatGPT, Claude, Gemini, and Perplexity?NoYesCan we measure share of model by query set?NoYesCan we tie AI visibility to pipeline or revenue reporting?LimitedYes, if attribution is built in
For a mid-size B2B SaaS team, that is the real buying question. Keep the SEO stack, but stop assuming it covers the model layer, where outputs shift by system, prompt wording, query intent, and source mix.
Targetlytics is built for that layer. It tracks brand mentions, citations, and recommendations across ChatGPT, Claude, Gemini, Perplexity, Meta, Grok, Bing Copilot, and Google AI Mode.
It also gives teams citation forensics, Share of Model analysis, LLM query reverse engineering, AI-readable infrastructure work, and AI revenue attribution. That makes the comparison more practical: which setup can explain why a competitor appears in AI answers and what your team should change next.
SEO still shapes what AI systems can find and trust on the open web. The next question is what an AI visibility platform actually does that SEO software does not.
What is an AI visibility platform, exactly?
An AI visibility platform is software built to measure how answer engines mention, cite, rank, and recommend brands across prompts and models. That differs from traditional SEO software because the object being measured is not only a webpage position; it is the brand’s presence inside generated answers.
A useful platform should track at least these units of analysis:
- Brand mentions: whether the company appears in an answer at all
- Citations: which URLs or domains the model references
- Recommendations: whether the model frames the brand positively, neutrally, or not at all
- Competitor displacement: which rival appears where your team expects to appear
- Share of model: how often your brand appears across a defined query set
- Query category performance: visibility by use case, industry, integration, problem, or comparison term
That last point is where many teams get stuck. A SaaS brand may look strong for branded prompts and weak for commercial or category prompts. Without measuring AI citations by query category, reporting says “we show up in AI,” while the sales team keeps hearing the competitor’s name on buying-intent searches.
When does a B2B SaaS team need a dedicated AI visibility platform?
A B2B SaaS team needs a dedicated platform when leadership asks questions that Search Console, Semrush, Ahrefs, and GA4 cannot answer. The clearest signal is when AI referrals, AI-assisted discovery, or answer-engine influence shows up in pipeline conversations before it shows up in standard dashboards.
You likely need dedicated AI visibility software for SaaS if any of these are true:
- Prospects mention ChatGPT, Perplexity, or Gemini during discovery calls
- Your team sees referral traffic from AI sources but cannot explain the source prompt or citation path
- Competitors appear in AI recommendations for category terms where you rank well in organic search
- Leadership wants board-ready reporting on AI visibility and ROI
- Content teams need to know which pages are actually being cited by models
- Product marketing wants proof of message uptake across answer engines, not just webpages
Mid-size B2B SaaS teams hit this point earlier than they expect because AI answers compress vendor shortlists. If the model recommends four tools and your brand is absent, “good SEO” is not enough comfort. The shortlist has already been formed.
Why SEO data alone cannot explain AI answer performance
GEO platform vs SEO tools is the wrong shorthand if it implies one replaces the other. The practical issue is that SEO data explains source visibility on the web, while AI visibility data explains answer behavior inside the model.
Here is where the split shows up:
- A page can rank well and still never be cited by a model
- A weak competitor can be cited because a third-party review, forum thread, or documentation page is easier for the model to parse
- Brand mentions can differ sharply across ChatGPT and Perplexity on the same commercial query
- Traffic can stay flat while recommendation share changes inside AI interfaces
That last case matters for executives. A content team may be improving pages that support model citation, but GA4 will not show the full effect if the user gets enough confidence from the answer itself to book a demo later through direct or branded channels. AI revenue attribution for SaaS needs more than clickstream analytics.
Which AI models should a platform track?
If the goal is AI visibility tracking across ChatGPT Claude Gemini and Perplexity, those four are the starting set, not the full list. B2B SaaS buyers should also look for coverage across Bing Copilot, Google AI Mode, Meta, and Grok if those systems matter to their market.
Model coverage should include:
- ChatGPT for mainstream buyer research behavior
- Perplexity for citation-heavy answer discovery
- Claude for long-form synthesis and research prompts
- Gemini for Google ecosystem visibility
- Bing Copilot for Microsoft workflow exposure
- Additional systems where your audience works or evaluates vendors
Targetlytics tracks mentions, citations, and recommendations across ChatGPT, Claude, Gemini, Perplexity, Meta, Grok, Bing Copilot, and Google AI Mode. For B2B SaaS teams, that matters because model behavior is not interchangeable. A brand can look dominant in one answer engine and nearly absent in another, which is why comparing brand presence in ChatGPT and Perplexity should be a default evaluation step, not an advanced feature.
Why “share of model” matters more than rank snapshots
Share of model analysis for B2B SaaS gives leadership a metric that fits how AI discovery actually works. Instead of asking whether one page ranked #3 on one query, it asks how often the brand appears across a meaningful query set inside the models that buyers use.
A useful share-of-model view should break down:
- Query category: branded, category, alternative, integration, pain-point, competitor comparison
- Model: ChatGPT, Claude, Gemini, Perplexity, and others
- Presence type: mention, citation, recommendation
- Competitor set: who appears with you and who replaces you
- Time period: week over week, month over month, campaign period
This is where probabilistic output becomes manageable. AI answers change, but a structured sampling approach turns changing outputs into trend data. Targetlytics uses N-Sampling across hundreds of queries per week, which is a stronger way to measure visibility than a single-prompt screenshot because it treats answer variance as a measurement condition, not noise to dismiss.
How reliable is AI visibility measurement when outputs change?
AI visibility measurement is reliable enough to guide decisions when the platform samples repeatedly across a defined prompt set, tracks changes over time, and separates one-off answer noise from repeat patterns. If a tool shows one prompt result and presents it as the full picture, the measurement is weak.
Reliable measurement should include:
- A fixed query library by intent and funnel stage
- Repeated runs rather than one-time checks
- Model-specific reporting, not blended averages
- Clear treatment of stochastic variation
- Trend views that show movement over time
- Exportable data for internal review
The right question is not “Can AI outputs vary?” They can. The right question is whether the platform’s methodology is good enough to measure direction and magnitude across that variance. For B2B SaaS teams, that means choosing a platform with an explicit sampling method, query grouping, and historical reporting.
Why competitors are cited in AI answers when your brand is not
The answer to why competitors are cited in AI answers is usually traceable. Citation forensics and citation path tracing can show whether the model preferred a competitor’s documentation, a third-party list, a review site, a community discussion, or a better-structured page on your own topic.
Common causes include:
- Competitor pages are easier for models to parse
- Third-party sites mention the competitor more often in category language
- Your site has weak entity clarity or fragmented product naming
- Key comparison and integration pages do not exist or are too thin
- The model relies on sources that cite your rival more directly
- Your content is visible in search but poorly formatted for AI extraction
This is where a dedicated platform earns its place. With citation forensics and LLM query reverse engineering, teams can move past “the competitor keeps showing up” and ask the useful question: which source path caused the recommendation, for which query cluster, in which model, and what page or mention should be fixed first?
Citation path tracing changes the action plan
Citation path tracing matters because knowing the cited URL is not enough. A buying team needs to know whether the path began on your site, a review platform, a partner page, a documentation hub, or a publisher that repeatedly shapes model answers in your category.
A practical workflow looks like this:
- Identify the query clusters where recommendation share is weak
- Pull the cited sources by model
- Group sources by type: owned, earned, partner, analyst, community, review
- Compare source patterns against the competitor set
- Decide whether the fix is content, digital PR, documentation, structured page design, or brand language consistency
This is also where generic “SEO for AI” advice falls apart. If Perplexity cites a third-party comparison page and Claude leans on documentation wording, the right fix is a source-specific intervention.
AI-readable infrastructure is now part of content performance
What AI visibility means for B2B SaaS is no longer limited to writing more category pages. It includes making the site easier for models to interpret, quote, and associate with the right commercial concepts.
Buyers should look for AI-readable infrastructure analysis that checks:
- Clear page-to-topic alignment
- Consistent brand and product entity naming
- Strong internal links between solution, use-case, and proof pages
- Documentation that answers implementation questions directly
- Comparison and alternative pages that reflect real buyer searches
- Clean page structure that surfaces definitions, evidence, and feature relationships
Targetlytics treats this as AI-readable infrastructure optimization, which gets to the real issue. The question is not only whether content exists. The question is whether answer engines can reliably parse what the company does, who it serves, and why it belongs in a recommendation set.
Hallucination detection and approval-controlled publishing matter more than they sound
A good AI search visibility software for SaaS platform should help teams catch incorrect brand descriptions and keep changes aligned with messaging. Hallucination detection matters because a model can mention your company while getting the category, pricing logic, customer fit, or competitor context wrong.
That creates two operational needs:
- Hallucination detection: identify recurring inaccuracies in model outputs
- Approval-controlled publishing: keep remediation work tied to approved messaging, product facts, and compliance standards
Many teams treat this as secondary to visibility tracking. In B2B SaaS, it is a sales and positioning issue. If a model recommends your brand for the wrong use case, sales inherits the cleanup.
Can AI visibility data be tied to pipeline and revenue?
Yes, AI revenue attribution for SaaS is possible, but only if the platform connects answer-engine exposure to downstream business reporting instead of stopping at mention counts. Leadership does not need another awareness metric in isolation; it needs a path from visibility to influenced pipeline.
Useful revenue reporting should connect:
- Query categories to high-intent buying themes
- Brand mentions and citations to referral or assisted sessions where available
- AI-sourced or AI-influenced opportunities to campaign and content changes
- Competitor displacement trends to pipeline risk or recovery
- Visibility gains to account, segment, or product-line reporting
Targetlytics includes AI revenue attribution in that workflow, which helps translate model visibility into executive reporting. For a CMO or demand generation lead, that is the difference between “AI exposure went up” and “enterprise evaluation queries now show higher recommendation share, and demo creation followed.”
How to compare AI visibility platforms quickly
Use this AI visibility platform comparison for B2B SaaS to make a shortlist fast: judge each vendor on coverage, methodology, reporting, and diagnosis. If a platform cannot tell you where your brand appears, why a competitor is cited, how results vary by model, and what your team should change next, it will add work instead of removing it.
CriterionAsk the vendorStrong answerWeak answerCoverageWhich models, query types, and competitors are tracked?Tracks ChatGPT, Claude, Gemini, Perplexity, Bing Copilot, Google AI Mode, Grok, and Meta, with views for branded, category, comparison, alternative-to, pricing, and use-case promptsCovers one or two models, limited prompts, or mention counts without competitor contextMethodologyHow do you measure outputs that change by run and by model?Uses repeated sampling, grouped query sets, and model-level reporting across hundreds of queries per weekRelies on one-off prompt checks, screenshots, or manual spot checksReportingCan both operators and leadership use the output?Separates mentions, citations, recommendations, and Share of Model; breaks results out by model, competitor, and query category; connects visibility to traffic, leads, or revenue viewsProduces a dashboard full of activity but weak on decision supportDiagnosisCan you explain displacement and show the fix path?Traces citation paths, shows source influence, flags hallucinated brand facts, and points to site or content changes that improve AI readabilityStops at tracking and leaves the team to guess why visibility is weak
For most mid-size B2B SaaS teams, coverage and methodology should decide the first cut. A polished dashboard means little if the platform misses the models your buyers use or cannot show whether a visibility change is real or just prompt noise.
This is where Targetlytics separates itself from SEO suites and brand monitoring tools. Search Console, Semrush, Ahrefs, and GA4 still matter, but they do not show brand mentions, citations, recommendations, citation paths, or Share of Model across ChatGPT, Claude, Gemini, Perplexity, Meta, Grok, Bing Copilot, and Google AI Mode.
Targetlytics is built for that missing layer. It combines model coverage with citation forensics, LLM query reverse engineering, AI-readable infrastructure work, and AI revenue attribution, so a team can move from “we are missing in AI answers” to “here is why, here is where, and here is what to change.”
The fastest trial structure is simple: one product category, three named competitors, and four query groups. Test category terms, alternative-to prompts, comparison prompts, and pricing or use-case prompts, then check whether the platform shows model-by-model visibility, citation differences by query type, and repeatability across sampling runs.
That trial should also produce an operating plan. If the output does not tell your SEO, content, and demand gen teams which source paths matter, where competitors are winning citations, and which AI-readability fixes to ship first, the platform is still acting like a tracker.
Targetlytics gives buyers a practical way to run that test. There is a free AI Visibility Audit, a free plan for limited tracking, a Starter tier at $99 per month with all LLMs included and a 14-day free trial, and a Professional tier at $249 per month that adds brand constitution, forensics, hallucination detection, and the Action Engine/GEO playbook.
A good buying question is blunt: after two weeks, can your team explain why competitors are recommended in AI answers, and can it show a plan to change that? If the answer is vague, keep looking.
Coverage is the next screen, because platform value drops fast when the models your buyers rely on are missing.
Coverage
Coverage means more than logos on a pricing page.
Check for:
- Which models are tracked
- Whether mentions, citations, and recommendations are measured separately
- Whether query categories can be grouped by use case or funnel stage
- Whether competitor benchmarking is built in
Methodology
Methodology is where weak tools get exposed.
Check for:
- Sampling frequency
- Repeated prompt runs
- Transparent treatment of answer variance
- Historical reporting depth
- Results drawn from broad query sets, not handpicked screenshots
Reporting
Reporting should work for both operators and executives.
Check for:
- Share of model analysis
- Model-by-model breakdowns
- Citation source exports
- Board-ready views for trend reporting
- Revenue or pipeline overlays
Actionability
Actionability decides whether the platform changes outcomes.
Check for:
- Citation forensics
- Query reverse engineering
- AI-readable infrastructure guidance
- Hallucination tracking
- Workflow support for content, SEO, and product marketing teams
What should a B2B SaaS buyer look for in a free audit or trial?
A free audit or trial in an AI visibility platform comparison for B2B SaaS should produce five decision-grade outputs: model-by-model visibility, query-category splits, citation paths, sampling details, and a clear link to reporting or pipeline review. If a vendor cannot give you those outputs on your own market terms, the trial is too shallow to support a demo or pricing decision.
What to request before the demoWhat the output should includeHow to judge itWhat it should decide nextModel-by-model visibility reportYour brand plus 3-5 named competitors run against the same query set across ChatGPT, Claude, Gemini, Perplexity, and any other tracked modelsCheck that every model used the same prompts and competitor set, with results shown side by side rather than as isolated screenshotsIf visibility gaps appear only in one or two models, ask for a focused walkthrough on those systems before you discuss plan sizeQuery-category breakdownResults grouped by query type such as alternatives, comparisons, category terms, integrations, pricing, and shortlist queriesLook for where absence is concentrated. A blended score can hide the fact that your brand is weak only on commercial-intent promptsUse the weak categories to decide whether you need an audit first, a content fix list, or a broader rolloutCitation forensicsThe pages, domains, or references connected to each recommendation, including why a competitor was cited when your brand was notGood output explains the source path behind the answer. Mention counts alone do not tell you what changed the recommendationIf the source path is clear, bring in content, product marketing, PR, or web teams before you spend on a larger subscriptionSampling and repeatability viewRepeated runs across a meaningful query set, with enough volume to show a pattern instead of a single lucky promptAsk how many queries are sampled each week, whether runs are normalized, and how variance is handled across modelsIf the method looks thin, keep the conversation at pilot level and do not buy on dashboard polishAI-readable infrastructure checkSpecific findings tied to crawlability, schema, markdown routing, llms.txt, or other site-readability issuesThe output should be specific enough that your web or technical team can act on it without rewriting the recommendationIf issues are concrete and fixable, move the vendor conversation toward implementation support rather than another overview callReporting and revenue connectionA view of visibility by query class, competitor set, or buying stage that can feed leadership reportingJudge whether the platform can move from “we were mentioned” to “where this affects pipeline review, attribution, or market coverage”If reporting is usable, then pricing should be judged as operating software, not a research tool
For a B2B SaaS team, the best trial starts with a tight brief. Give the vendor 20-50 real queries, 3-5 direct competitors, and one live buying question such as “Why do we disappear on alternative-to queries?” or “Which model cites us least on pricing comparisons?”
Then ask for the output in a format your team can use the same week: a scorecard by model, a breakdown by query category, a citation-path readout for lost recommendations, and a short action list split into on-site, off-site, and reporting fixes. That package tells you far more than a polished product tour.
Targetlytics gives buyers a concrete way to run that test. The free AI Visibility Audit can be used to request model coverage across ChatGPT, Claude, Gemini, Perplexity, Meta, Grok, Bing Copilot, and Google AI Mode, plus query-category analysis, citation forensics, AI-readable infrastructure findings, and a strategy session built around your own competitor set.
Its trial tiers also make comparison easier. A buyer can start on the free plan for limited ChatGPT coverage, use the 14-day Starter trial to check multi-model visibility at a lower volume, or move to Professional if the evaluation needs brand constitution, forensics, hallucination detection, and a GEO action plan.
Use the audit to answer a purchase question, not to admire a dashboard. If Targetlytics can show where your brand drops out, why a competitor gets cited, how often that pattern repeats, and what your team should change next, you have enough to judge whether it belongs in your stack and where it fits in the category.
Where Targetlytics fits in the category
Targetlytics fits the GEO platform vs SEO tools decision as the dedicated AI visibility layer for B2B SaaS teams that already have SEO and analytics in place. It does not replace Search Console, Semrush, Ahrefs, or GA4. It answers the questions those systems do not cover.
The platform centers on:
- Brand mentions, citations, and recommendations across major AI models
- Share of Model analysis
- Citation forensics
- LLM query reverse engineering
- AI-readable infrastructure optimization
- AI revenue attribution
- Published pricing tiers and a free audit path
What makes that combination useful is the operating logic behind it. This is not a monitoring widget bolted onto SEO reporting. It is a working loop: where the brand appears, why it appears, why it does not, what source path drove the answer, and what commercial result followed.
The practical buying threshold for mid-size SaaS teams
A mid-size B2B SaaS team usually needs a dedicated AI visibility platform once AI answers affect shortlist creation, competitor comparisons, or leadership reporting, and the current stack still cannot explain why your brand is or is not being recommended. That is the practical threshold in any AI visibility platform comparison for B2B SaaS.
- Are buyers using ChatGPT, Perplexity, Claude, Gemini, or other answer engines before they ever reach your site?
- Are competitors showing up for high-intent category, comparison, or replacement queries?
- Can your team identify which sources and citations are driving those answers?
- Can leadership see AI visibility in terms tied to pipeline or revenue, rather than traffic alone?
If the answer is no on the last two questions, Search Console, Semrush, Ahrefs, and GA4 are still useful, but they are no longer enough on their own. They show how your site performs on the web; they do not show how models mention your brand, which competitor gets cited instead, or how that varies across AI systems.
That is where a dedicated platform such as Targetlytics becomes relevant for B2B SaaS teams. It tracks brand mentions, citations, and recommendations across ChatGPT, Claude, Gemini, Perplexity, Meta, Grok, Bing Copilot, and Google AI Mode, then adds citation forensics, Share of Model analysis, AI-readable infrastructure work, and AI revenue attribution so teams can move from guesswork to operating discipline.
A quick way to test fit is to run a free AI Visibility Audit, then check what it reveals about model coverage, citation sources, visibility gaps, and whether the reporting is useful to marketing leadership. If that audit surfaces missing brand presence, competitor displacement, or unanswered citation questions, the buying case is usually already in front of you.
You can start with a free AI visibility audit and book a call to review the findings. You can also start for free, with paid plans offering a 14-day trial. The test is simple: use a real buying-question set, preserve the evidence, and make no content change that the audit cannot explain.