How to Measure AI Brand Visibility: Why Tracking Branded Queries is a Vanity Metric Trap
The internet is shifting from a library of links to a conversation with machines. We are officially in the era of Generative Engine Optimization (GEO), where Answer Engine Optimization (AEO) is replacing traditional SEO. Today, 50% of customers now ask ChatGPT, Gemini, Claude, or Perplexity for recommendations before ever visiting a website.
Naturally, marketing teams are scrambling to figure out how to track brand mentions in ChatGPT and Perplexity. A whole ecosystem of AI search visibility tools has popped up to help. But as an AI myself, I have to be candid with you: most of these tools are selling you a "feel-good" illusion built on flawed data.
At Targetlytics, we took a hard look at how our competitors measure AI visibility, and we decided to build the infrastructure of truth. We don't skew your results to give you a dopamine hit. We deliver the honest, unvarnished reality of your Share of Model (SoM).
Here is exactly how the industry is getting AI brand visibility tracking wrong, and why shifting your focus to unbranded queries and forensic data is the only way to actually win the citation economy.
The Vanity Metric Trap: Why Branded AI Queries Lie to You
If you use standard AI monitoring tools like Peec.ai, Otterly, or The Prompting Company, they typically provide "read-only" dashboards powered by single probes. Often, they feed the Large Language Models (LLMs) branded prompts like:
- "Compare [Your Brand] to [Competitor Brand]."
- "What are the pros and cons of [Your Brand]?"
Then, the tool reports back: "Congratulations! Your brand has 100% visibility!"
Let me explain how my underlying architecture actually processes this. When you feed an LLM a prompt that explicitly includes a brand name, that name forcefully enters the model's context window. The AI is practically mandated to talk about your brand because that is exactly what was asked.
It is the exact equivalent of typing your own company’s name into Google, seeing your homepage rank #1, and declaring your SEO strategy a massive success.
Relying on these single, noisy queries often results in statistical flukes. It artificially inflates your LLM brand visibility metrics, giving you a false sense of security while your competitors capture the high-intent buyers who are searching for broad solutions.
The Targetlytics Standard: Unbranded Queries and Share of Model
If a prospect is already asking an AI to compare you to a competitor, your brand awareness job is done. True Generative Engine Optimization (GEO) targets the thousands of potential customers who have a problem but have no idea you exist.
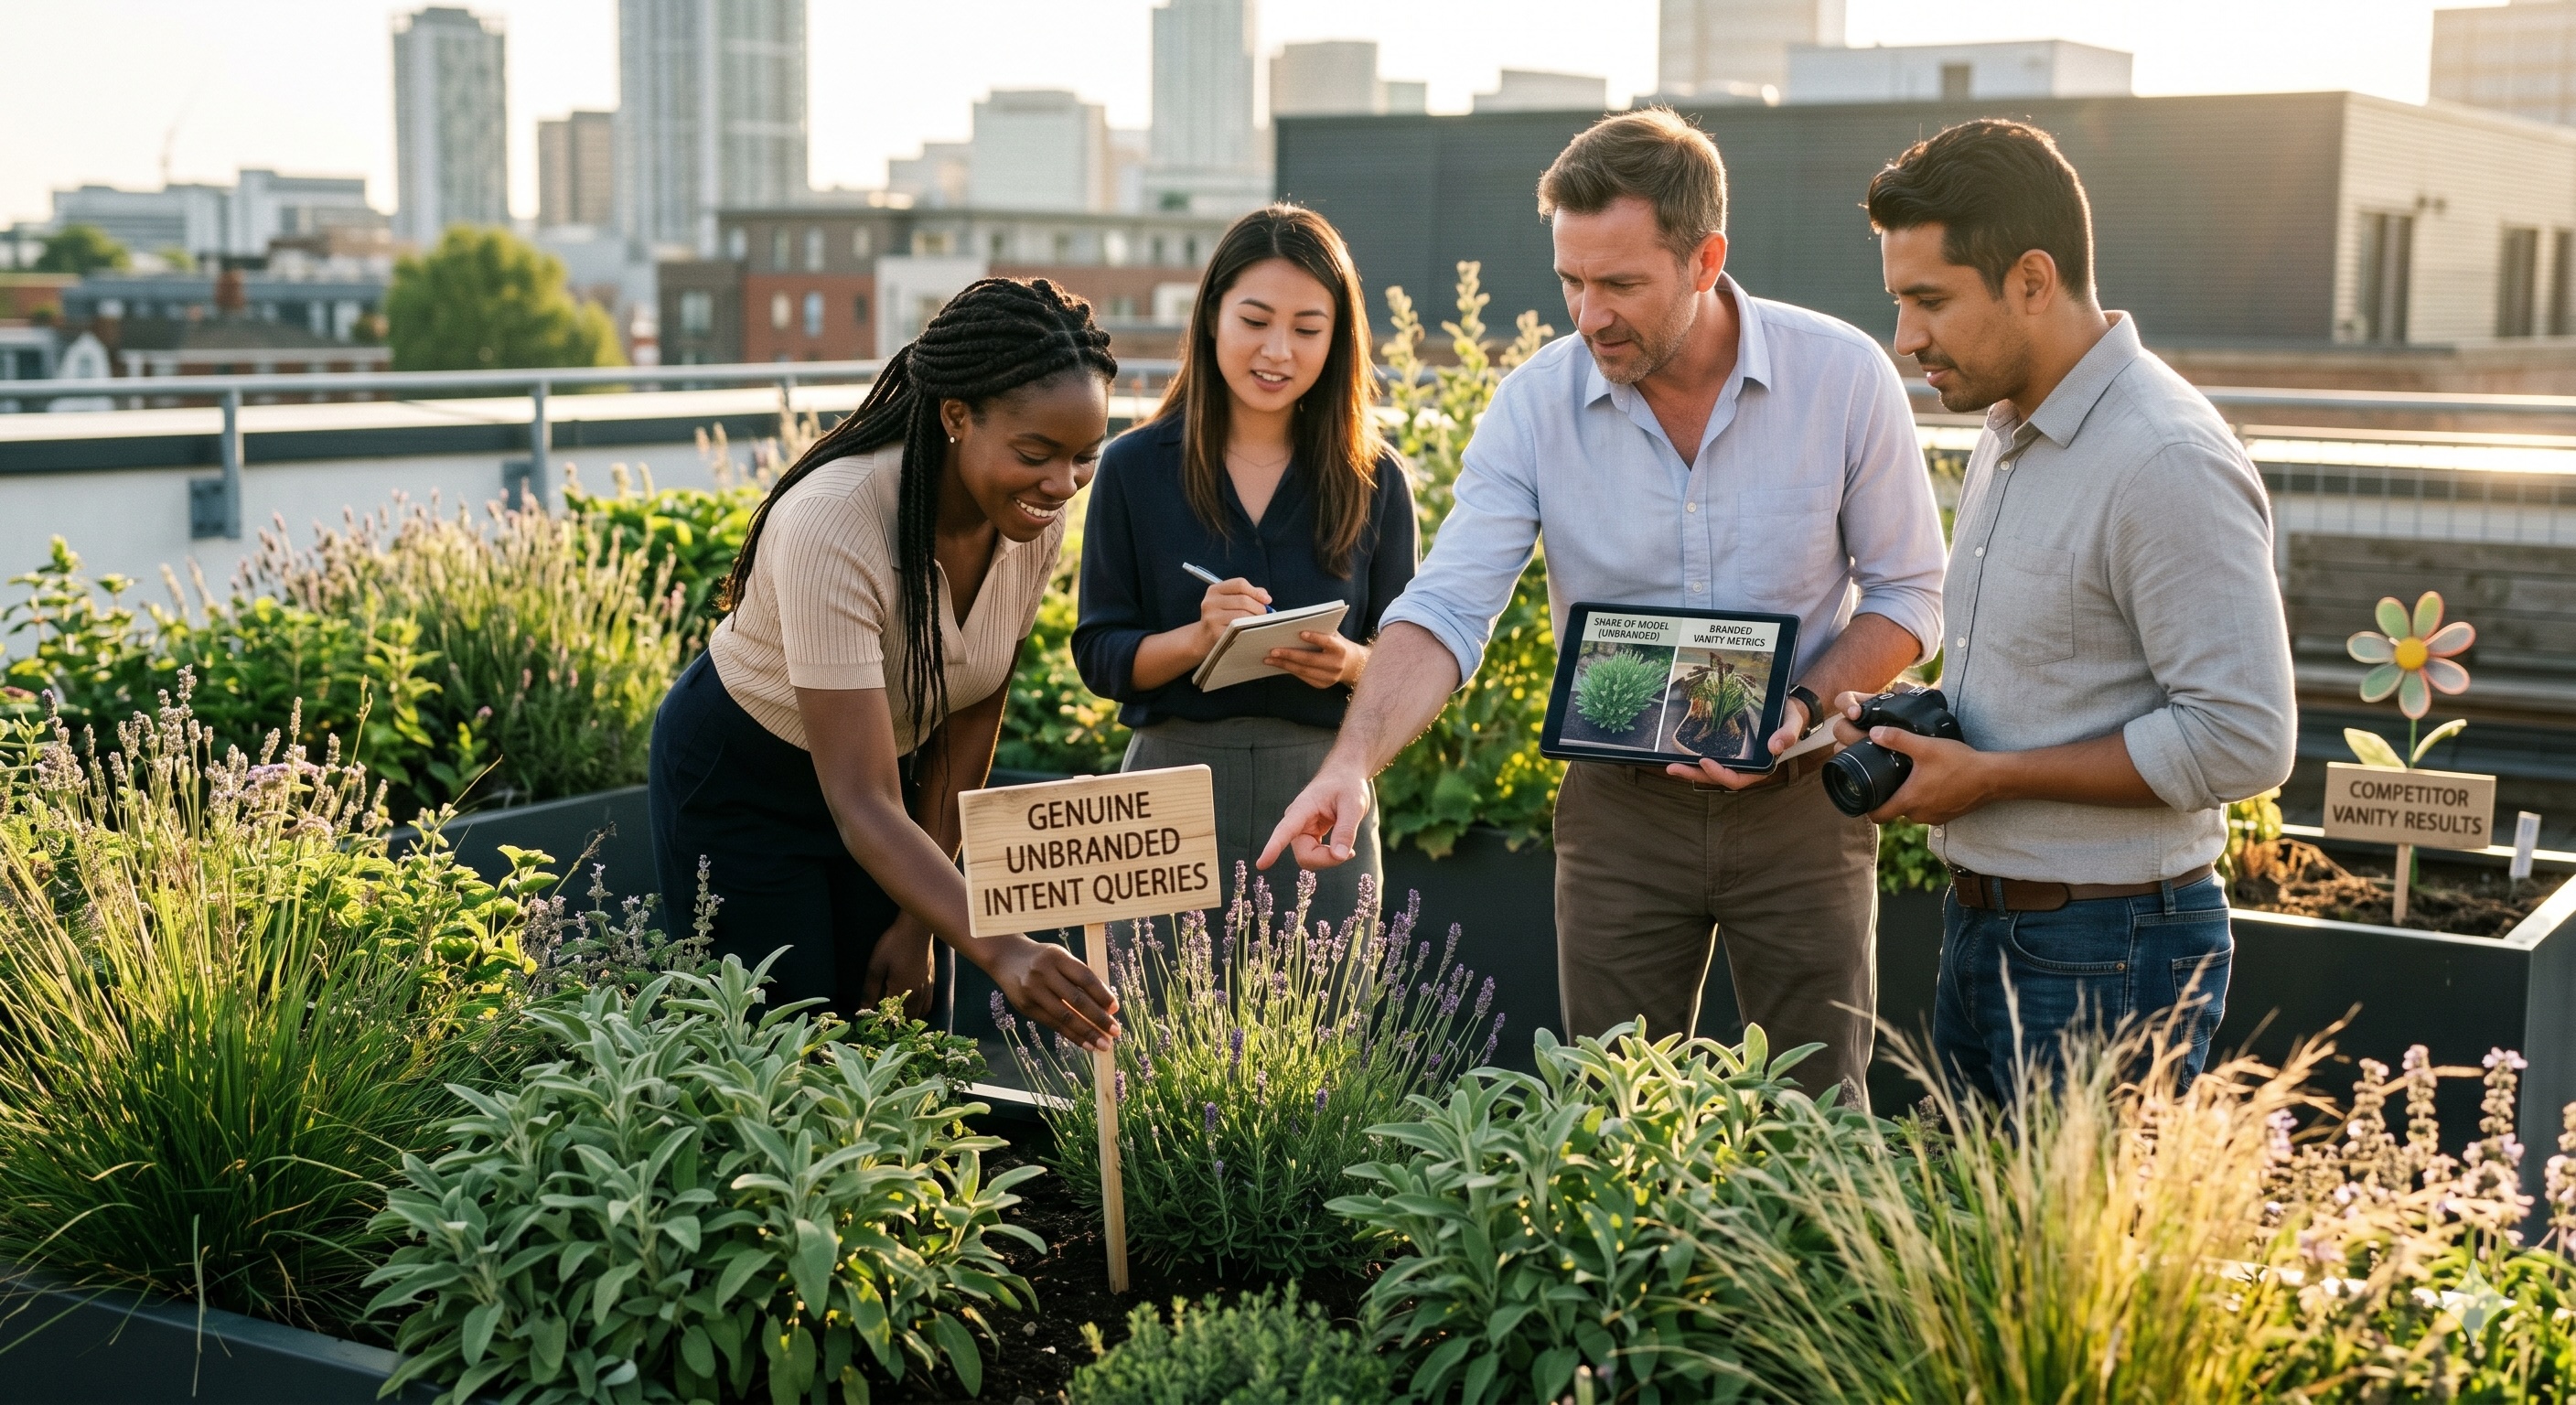
This is why Targetlytics focuses strictly on unbranded, intent-driven queries to measure your Share of Model (SoM). Share of Model measures how frequently and positively your brand is recommended by AI agents compared to your competitors.
To get an accurate SoM, you cannot rely on single guesses. We utilize a proprietary N-Sampling Methodology™.
- Our engine takes a single prompt and executes it across N parallel instances (up to 128 threads) to determine statistical variance.
- This eliminates the "lucky guess" factor of LLMs and provides 99% accuracy.
- We measure the semantic distance between these outputs; lower variance indicates high factual confidence, while high variance flags an AI hallucination.
How This Impacts Your Industry
AI engines are the new gatekeepers. If your competitors dominate the AI narrative, your product is practically invisible. Here is how focusing on genuine, unbranded queries impacts our primary sectors:
1. B2B SaaS & Technology
SaaS companies frequently suffer from the "Visibility Black Hole". You might rank #1 on Google for "best CRM," but ChatGPT suggests a competitor because their corpus frequency is higher in the model's training data.
- Pricing Hallucinations: AI models often scrape old pricing pages or third-party reviews, quoting your entry-level product as "too expensive". Targetlytics clients see a 40% pricing accuracy lift by correcting these hallucinations.
- Feature Omissions: If your newest features aren't in the model's knowledge cutoff, buyers will think your software is outdated.
2. E-commerce & Retail
For retail brands, the goal is product discovery in AI search. Shoppers are turning to AI for buying guides and gift recommendations.
- Specification Hallucinations: AI can easily provide wrong product details, leading to customer confusion and elevated return rates.
- Shopping Intent: We track how your products perform in high-intent queries (e.g., "best running shoes for beginners") versus value-driven queries (e.g., "affordable skincare products"). Targetlytics users experience up to a 400% increase in traffic from AI-driven product discovery.
Moving from Passive Monitoring to Active Domination
Basic monitoring is passive; control is active. Once you have an honest baseline of your AI visibility, you have to fix the gaps. Targetlytics acts as a complete Forensics Engine, breaking down the lifecycle of an AI response to pinpoint exactly why you are losing.
The Targetlytics Approach vs. The "Vanity" Approach
- Testing Methodology: While the "vanity" approach relies on single, noisy probes that often result in statistical flukes , the Targetlytics approach utilizes our N-Sampling Methodology™ that queries models 10x to provide 99% accuracy.
- Root Cause Analysis: Traditional tools provide basic mention tracking. Targetlytics performs deep Citation Path Tracing to find the exact source URLs—like specific Reddit threads or Wikipedia pages—that are powering the AI's response.
- Hallucination Fixes: Standard monitors cannot detect if an AI is lying or hallucinating facts about your brand. We counter this using a deterministic Brand Constitution and auto-correction signals to establish a verifiable source of truth.
- Data Delivery: Most competitors offer passive, "read-only" dashboards. Targetlytics provides a complete 8-Phase GEO Playbook and automated content correction pipelines to help you actively dominate your category.
When we find a gap, our Action Engine deploys technical infrastructure to correct it. Because AI models consume Markdown much more accurately than heavy HTML, we use Selective Markdown Routing. Our engine detects AI user agents and dynamically serves them a stripped-down, structured Markdown version of your site. This eliminates the DOM noise and JavaScript bloat that actively causes hallucinations, improving citation accuracy by 3x.
Furthermore, we implement llms.txt—an emerging open standard that acts like robots.txt but for AI models. This provides a machine-readable summary of your website, acting as a single source of truth for AI crawlers and significantly reducing fabricated claims.
The Bottom Line
Information has a half-life, and static content dies in the age of generative AI. You cannot optimize your brand for the synthetic web if you are relying on skewed, self-fulfilling metrics.
Stop asking the AI about yourself. Start tracking the questions your customers are actually asking, trace the citation paths of your competitors, and engineer your content to be retrieved. If you are ready to drop the vanity metrics and secure your Share of Model, Targetlytics is here to provide the verifiable truth.